Abstract
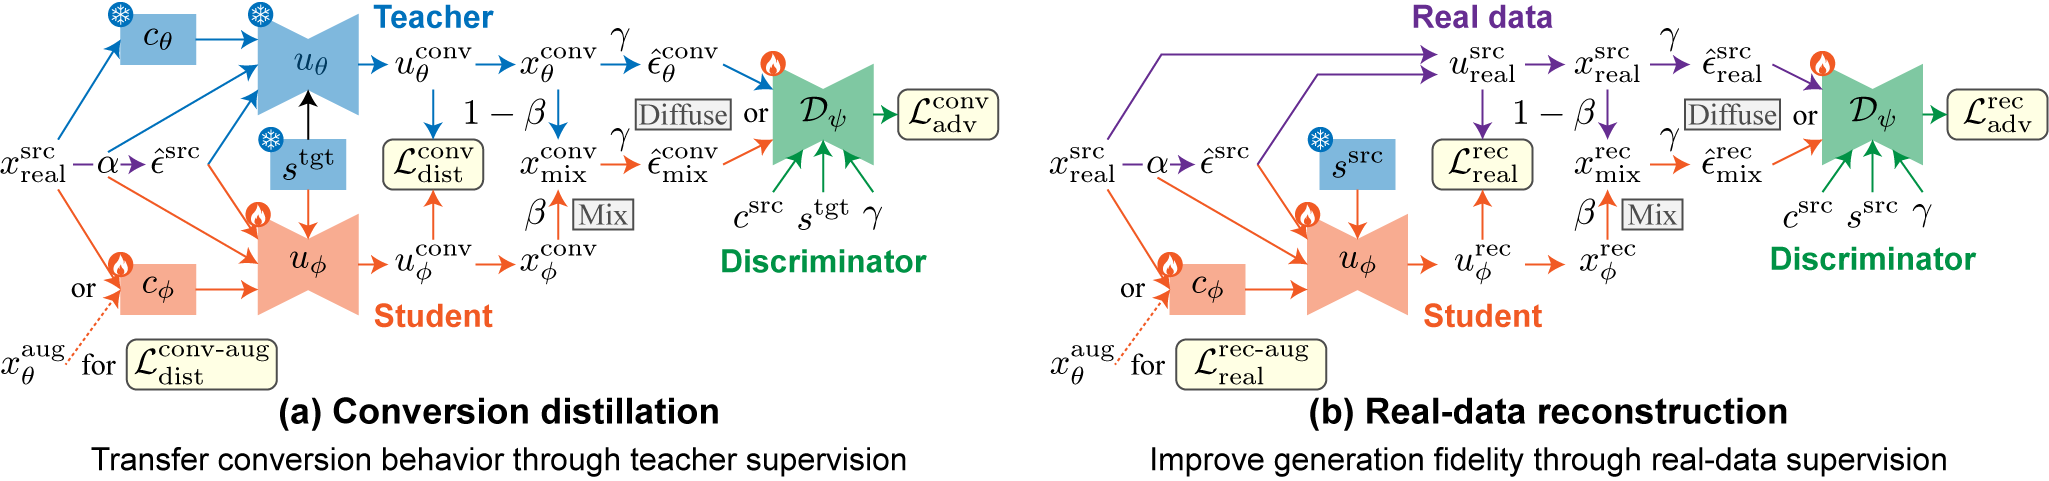
Flow-matching approaches to voice conversion (VC) have gained attention owing to their high speech quality and strong speaker similarity. Among them, one-step models such as MeanVoiceFlow are particularly attractive because they enable efficient inference; however, their reliance on a computationally intensive content encoder remains a bottleneck. We therefore propose MeanVoiceFlow2, a framework that jointly optimizes a flow-based conversion module and a computationally efficient content encoder. The model is trained through conversion distillation using MeanVoiceFlow and the reconstruction of real data. We further incorporate diffusion-GAN training with sample mixing and teacher-guided conditioning augmentation to enhance realism and disentanglement. Experiments on zero-shot VC showed that MeanVoiceFlow2 achieved higher perceptual quality and approximately 9 times faster inference than MeanVoiceFlow while maintaining comparable speaker similarity.
Contents
Results
Results on VCTK dataset (Table 4)
| Source | Target | DiffVC | MVF | MVF2 (ours) | FVG2 | |
|---|---|---|---|---|---|---|
| Speed↑ | Slow (×0.04) | (×1) | Fast (×9) | Fast (×9) | ||
| Requires pretrained vocoder for training |
No | No | No | Yes | ||
| Female → Female | ||||||
| Female → Female | ||||||
| Male → Male | ||||||
| Male → Male | ||||||
| Female → Male | ||||||
| Female → Male | ||||||
| Male → Female | ||||||
| Male → Female |
Results on LibriTTS dataset (Table 5)
| Source | Target | MVF | MVF2 (ours) | |
|---|---|---|---|---|
| Speed↑ | (×1) | Fast (×9) | ||
| Female → Female | ||||
| Female → Female | ||||
| Male → Male | ||||
| Male → Male | ||||
| Female → Male | ||||
| Female → Male | ||||
| Male → Female | ||||
| Male → Female |
Citation
@inproceedings{kaneko2026meanvoiceflow2,
  title={MeanVoiceFlow2: Joint Optimization of Mean Flow and Content Encoder for Fast One-Step Zero-Shot Voice Conversion,
  author={Kaneko, Takuhiro and Kameoka, Hirokazu and Tanaka, Kou and Kondo, Yuto},
  booktitle={Interspeech},
  year={2026},
}